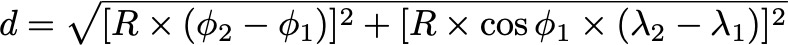Moved

Moved. See https://slott56.github.io. All new content goes to the new site. This is a legacy, and will likely be dropped five years after the last post in Jan 2023.

Showing posts with label Design Principles. Show all posts

Tuesday, December 13, 2022

On Algorithm Design

Some background: FAERIE DUST™, Obstinate Idiocy, Obstinate Idiocy, Expanded, and even Permutations, Combinations and Frustrations. I want to set up algorithm design as the diametric opposite of Obstinate Stupidity. To do that, let's look at Obstinate Stupidity.

The theme? 

We did something wrong, and we don't want to fix it.

I emphasize this because it takes many forms. Another common variant is "We can't afford to continue the way we are, but we can't afford the time to fix it, either." Sometimes, "Management wants this fixed, but we don't have any budget." You know how it is.

The current go-round is someone who has an algorithm of intensely stupid (and largely irrelevant) complexity. See My algorithm performs badly, do I need asyncio?

The situation is touchy. They have pre-reasoned an answer -- asyncio -- and they're looking for (a) confirmation that they're obviously right and (b) help rewriting something needlessly complex to somehow be faster even when it's compute-bound. Specifically, they want Faerie Dust.

Frivolous Complexity

How do I know it has needless, frivolous complexity?

Here are two symptoms.

  1. The problem has a lot of context. In thise case, there's a hierarchy. The hierarchy may seem irrelevant, but it has this mind-numbingly complex back-story, that they can't seem to ignore or abstract out of the essential problem. There's a (large) number of details that don't really explain what the hierarchy means or why it has to be preserved. but somehow make it essential.
  2. The problem can only be described by repeating the legacy algorithm. 

Let's dwell on this second symptom for a moment. We have two competing issues:

  • The legacy algorithm is too slow. AND,
  • There's no other way to describe the problem.

This should make it clear they are looking at asyncio as a kind of Faerie Dust that will magically make the bad algorithm good. Without fixing the bad algorithm.

I want to emphasize the existence of details which can neither be explained nor removed. The hierarchy must be there simply because it must be there. Bizarre complications to walk the hierarchy are, therefore, essential even if no one can explain them.

Algorithm Design

To actually improve the processing they need a new algorithm.

I can't emphasize this enough: they need a new algorithm. (This often means a new data structure.)

"Tuning" in any form is nothing more than nibbling around the edges to make a bad algorithm run 15% faster.

Rewriting may replace \(\textbf{O}(2^n)\) with \(\textbf{O}(n \log n)\). This would be dramatically better. From seconds to milliseconds. You know, 1,000% faster.

There's a disciplined approach to this. Here are the steps.

  1. Write the post-condition for the processing as a whole.
  2. Write code that achieves the post-condition. (This may involve decomposing the big problem into sub-problems, each of which is approached by the same two-step process.)

The intensely painful part of this is creating the post-condition.

I suggested they "write an assert statement that must be true when the algorithm has completed, and computed the right answer."

Hahahah.

What an idiot I was.

They didn't know how to write an assert statement. And at this point, they stopped. Brick Wall. Dead in the water. Cannot proceed. Done. Failed.

The assert statement has become the end-of-the-line. They can't (or won't) do that. And they won't ask about it.

Me: "Do you have a question?"

Them: "I have to think before I can even begin to ask a question."

Me: "How about think less and ask more. Do you have trouble writing the word assert? What's stopping you?"

Them: [silence]

Okay.

Post-Conditions

The post-condition is true when you're done. Let's look at my favorite, M must be the maximum of A and B.

\[M \geq A \textbf{ and } M \geq B\]

This becomes an assert statement through (what seems to me, but boy was I wrong) the following kind of translation.

assert M >= A and M >= B, f"Algorithm Failed {M=} {A=} {B=}"

Again, I acknowledge I was wrong to think creating an assert statement from a post condition was in any way clear. It's absolutely bewilderingly impossible.

It's also important to note that the above condition is incomplete. The value \(M = A+B\) will also satisfy the condition. We need to test our test cases to be sure they really do what we want.

We really need to be more complete on what the domain of values for \(M\) is.

\[M = A \textbf{ or } M = B \textbf{ and } M \geq A \textbf{ and } M \geq B\]

We could rewrite this slightly to be

\[M \in \{A, B \} \textbf{ and } M \geq A \textbf{ and } M \geq B\]

This version directly suggests a potential set comprehension to compute the result:

M = {m for m in {A, B} if m >= A and m >= B}.pop()

This is the advantage of writing post-conditions. They often map to code.

You can even try it as pseudo-SQL if that helps you get past the assert statement.

SELECT M FROM (TABLE INT(X); A; B) WHERE M >= A AND M >= B

I made up a TABLE INT(X); A; B to describe a two-row table with candidate solutions. I'm sure SQL folks have other sort of "interim table" constructs they like.

The point is to write down the final condition. 

I'll repeat that because the folks I was trying to work with refused to understand the assert statement.

Write down the final condition.

The Current Problem's Post-Condition

The problem at hand seems to involve a result set, \(R\), pulled from nodes of some hierarchy, \(H\), \(R \subseteq H\). Each element of the hierarchy, \(h \in H\) has a set of strings, \(s(h)\). It appears that a target string, \(t\), must be a member of \(t \in s(r), r \in R\). I think.

Note that the hierarchy is nothing more than a collection of identified collections of strings. The parent-childness doesn't seem to matter for the search algorithm. Within the result set, there's some importance to the tier of the hierarchy, \(t(h)\), and a node from tier 1 means all others are ignored or something. Can't be sure. (The endless backstory on the hierarchy was little more than a review of the algorithm to query it.)

If any of this is true, it would be a fairly straightforward map() or filter() what could be parallelized with dask or concurrent.futures.

But we can't know if this really is the post-condition until someone in a position to know writes the post-condition.

Things To Do

The post-condition defines the results of test cases. The assert statement becomes part of the pytest test cases. In a kind of direct copy-and-paste process to shift from design aid to test result condition.

Currently, the algorithm they have seems to have no test cases. They can't write a condition to describe correct answers, which suggests they actually don't know what'a correct.

If they wrote test cases, they might be able to visualize an assert statement that confirms the test worked. Might. It appears to be asking a lot to write test cases for the legacy algorithm.

Indeed, if they wrote a conditional expression that described the results of any working example, they'd have taken giant steps toward the necessary assert statement. But that's asking a lot, it appears.

And Then What?

Once you have a target condition, you can then design code to satisfy some (or all) of the target condition. Dijkstra's A Discipline of Programming has a thorough description of the "weakest precondition" operator. It works like this:

  1. Imagine a statement that might satisfy some or all of your post-condition.
  2. Substitute the effect of the statement into the post-condition. 
  3. What's left is the weakest pre-condition for that statement to work. It's often the post-condition for a statement must precede the statement you wrote.

You write the program from the desired post-condition moving forward until you get a weakest pre-condition of True. Back to front. From goal to initialization.

Post-condition gives you statements. Statements have pre-conditions. You iterate, writing conditions, statements, and more conditions.

(You can also spot useless code because the pre-condition matches the post-condition.)

For the silly "maximum" problem?

Try M := A as a statement. This only works if A >= B. That's the pre-condition that is derived from substituting M = A into the post-condition.

Try M := B as a statement. This only works if B >= A. That's the pre-condition that is derived from substituting M = B into the post-condition.

These two pre-conditions describe an if-elif statement. 

Note that this feels weirdly arbitrary and exploratory. It's a kind of empiricism where we try statements and see if they're helpful. There don't need to be any constraints. The post-condition is all that's required to explore the space of statements that might work, or at least might help.

Of course, we're not stupid. And we're lazy. We don't search the infinite space of statements. We can often imagine the statements without a lot of complex work. The formal weakest pre-condition process is necessary to confirm our intuition. Or to assert that something is free of astonishing side-effects.

It all depends on one thing: a clear, formal statement of the post-condition.

Since I made the mistake of describing the post-condition as a line of code, we've hit some kind of brick wall related to "I won't write code." Or "I don't want to be seen writing code." or "I don't want you to critique my code." 

Dunno.

Tuesday, July 27, 2021

SOLID Coding in Python

SOLID Coding in Python by Mattia Cinelli.

Download Medium on the App Store or Play Store

This was fun to read. It has some nice examples. 

I submit that the order of presentation (S, O, L, I, D) is misleading. The acronym is fun, but awkward.

My LinkedIn Learning course covers these in (what I think is) a more useful order.

  1. Interface Segregation. I think this is the place to start: make your interfaces as small as possible.
  2. Liskov Substitution. Where necessary, leverage inheritance.
  3. Open/Closed. This is a good quality check to be sure you've followed the first two principles well.
  4. Dependency Injection. This is often about test design and future expansion. In Python, where everything really happens at run time, we often fail to parameterize a type properly. We often figure that out a test time, and need to revisit the Open/Closed principle to get things right.
  5. Single Responsibility is more of a summary of the previous principles than a distinct, new principle. I think it comes last and should be treated as a collection of good ideas, not a single idea.

I think time spent on the first three -- Interface Segregation, Liskov Substitution, and the Open/Closed principle -- pay off tremendously. The ILODS acronym, though, isn't as cool as SOLID.

The "Single Responsibility" suffers from an ambiguous context. At one level of abstraction, all classes have a single responsibility. As we dive into details, we uncover multiple responsibilities. The further we descend into implementation details the more responsibilities we uncover. I prefer to consider this a poetic summary, not the first step in reviewing a design.

Tuesday, June 15, 2021

Architectural Boundaries: Which Package/Module/Class Owns That Responsibility?

 The SOLID design principles beat the design boundary issue to death. Here are the principles in my preferred order. (See https://www.linkedin.com/learning/learning-s-o-l-i-d-programming-principles

  1. Interface Segregation -- minimize the boundaries. Do this first.
  2. Liskov Substitution -- keep the boundaries consistent. Do this for hierarchies.
  3. Open/Closed -- keep the boundaries stable and allow subclasses. 
  4. Dependency [Inversion] Injection -- keep the implementation separate from the design.
  5. Single Responsibility -- This is essentially a summary of the above four principles.

The point here is that these principles are pleasantly poetic, but there are those edgy cases where an interface can go either way.

Specifically, here's an Edgy Case that can go either way.

We're reading GPX (GPS Exchange) data. See https://www.topografix.com/GPX/1/1/

Associated with this is what's known as the Lowrance USR file format. A lot of devices include the same (or similar) underlying software, and can exchange waypoint and route information in USR format.

We have this as part of the underlying model.

  • The underlying Angle as an abstraction. This has two subclasses:
    • Latitude. An angle with "N" and "S" for its sign, conventionally shown as a two-digit number of degrees: 25°42.925′N
    • Longitude. An angle with "E" and "W" for its sign, conventionally shown as a three-digit number of degrees: 080°13.617′W
  • A Point (or LatLon) is a two-tuple, tuple[Lat, Lon].

A waypoint includes name, description, a time-of-last-update (TOLU), and display symbol to be used. It may also include a GUID to track name changes and assure uniqueness in spite of repeated names.

So far, so good. Nothing too edgy there. "Where's the problem?" you ask.

The problem is representation.

In GPX files, latitude and longitude are float values in degrees. You'll see this: <wpt lon="-80.22695124" lat="25.7154147">...</wpt>.

To do any useful computation, they need to be radians. Or a geocode that supports proximity comparisons, like OLC.

And. If you work with a CSV export from a tool like OpenCPN, then you get strings. This can be any combination of degrees and minutes or degrees, minutes, and seconds. And, depending on the software, there may be either ° or º for the degrees. Can't tell the apart? One is U+00B0, the DEGREE SIGN. The other is U+00BA, the MASCULINE ORDINAL INDICATOR. Plus, of course, everyone uses apostrophe (') and quote (") where they should have used prime (′) and double prime (″). These are easy regular expression problems to solve.

This leads to a class like the following:

class Angle(float):
@classmethod def fromdegrees(cls, deg: float, hemisphere: Optional[str] = None) -> "Angle": ...
@classmethod def fromstring(cls, value: str) -> "Angle": ...

This Angle class converts numbers or strings into useful values; in radians internally. Formatted in degrees externally.  (And yes, this gets a warning from Python 3.9 that we can't usefully extend float like this.)

The problem is USR files. 

In USR files, they use millimeter mercator numbers for latitude and longitude. These are distances from the equator or the prime meridian. Because they're in millimeters, an integer will do nicely. A little computation is done to extract degrees (or radians) from these values.

SEMIMINOR_B = 6_356_752.3142

lon = round(math.degrees(mm_lon / SEMIMINOR_B), 8)
lat = round( math.degrees(2 * math.atan(math.exp(mm_lat / SEMIMINOR_B)) - math.pi / 2), 8 )

These aren't too bad. But.

Here's the question.

Where does this belong? Is it part of the underlying Angle class? It is separate?

Where does Millimeter Mercator representation belong?

This raises a secondary question: Where does ANY representation belong?

Do we separate the essential object (an angle in radians, a float) from all representation questions? If so, how do we properly bind value and representation at run time? 

Is our app full of complex mixins to bind the float with representation choices?  class Latitude(float, DMS, MM, etc.): pass. This seems potentially annoyingly complex: we have to make sure names don't collide, when defining all these aspects separately.

I think the representation for latitudes and longitudes *is* the essential problem here. The math (i.e. computing the loxodromic distance between points) is trivially separated from all of these representation concerns. 

If we buy into the centrality of representation issues, then, we're down to the following argument.

Resolution: millimeter mercator belongs in the Angle class.

Affirmative: it's yet another representation of an angle's value. 

Negative: it's not used outside USR files and belongs in the USR file parser module.

Affirmative Rebuttal: None of the other representations in Angle are tied specifically to a file format.

Negative Rebuttal: Because the other formats (float, string) are intermixed in CSV files and text displays, making them "widely used." While float is used consistently in GPX, this encoding is a pleasant exception that relies on widely-used encodings.

Okay. We seem to have conflicting goals here. Some representation is a generic thing that crosses file formats and some representation is localized to a specific file format and not reused.

The SOLID design principles don't help chose between these designs. Instead, they provide post-hoc justification for the design we chose.

We can exploit the SOLID principles in a variety of ways. Some Examples.

  • We could claim that LatitudeMM is a subclass of Latitude with the MM conversions mixed in. Open/Closed. Liskov Substitution. 
  • We could claim that Latitude has several load/dump strategies available, including Load from MM. Open/Closed. Dependency is Injected at run-time.

Sigh.

Prior Art

Methods like __str__() and __repr__() are generally considered part of the essential class. That means the most common string representations need to be provided. The parsing of a string, similarly, is the constructor for  an instance of the float class.

So. Some representations are part of the class. Clearly, however, not all representations are part of the class. Representation codecs like pickle, struct, or ctype are kept separate.

I'm going to make the case that there's a very, very fine line between unique and non-unique-but-not-widely-used aspects of a class of objects. And, in this specific case, the millimeter mercator should be kept separate.

I'm going to rely on other representations like PlusCode (also called OLC) as yet another obscure representation and insist these aren't essential to the class. Indeed, I'm going to suggest that proximity-friendly geocoding is clearly separate because it's a hack to replace complex distance computations with substring comparisons. 

Tuesday, June 30, 2020

Over-Solving or Solving Problems You Don't Have

Sometimes we call them "Belt and Braces" solutions. As a former suspenders person who switched to belts, the idea of wearing both is a little like over-engineering. In the unlikely event of catastrophic failure of one system, your pants can still remain properly hoist. There's a weird, but defensible reason for that. Most over-engineering lacks a coherent reason. 

Sometimes we call them "Bells and Whistles." The solution has both bells and whistles for signaling. This is usually used in a derogatory sense of useless noisemakers, there for show only. Again, there's a really low-value and dumb, but defensible reason for this. 

While colorful, none of this is helpful for describing over-engineered software. Over-engineered software is often over-engineered for incoherent and indefensible reasons.

Over-engineering generally means trying to solve a problem that no user actually has. This leads to throwing around irrelevant features.

Concrete Example

I lived on a boat. I spent a fair amount of time fretting over navigation. 

There are two big questions: 
  1. How far apart are two points, really. 
  2. What's the real bearing from one point to another.
These are -- in some cases -- easy to answer.

If you have a printed, paper chart at the right scale, you can use dividers to compute a distance. It's actually a very easy task. Similarly, you can read the bearing off the chart directly. There's a trick to comparing a course to a nearby compass rose, but it's easy to learn and very accurate.

Of course, we don't want to painstakingly copy our notes from a paper chart to a spreadsheet to add them up to get total distance. And then fold in speed to get time and fuel consumption. These summary computations are a pain.

What you want is to do all of this with a computer.
  1. Plot the points using a piece of software like OpenCPN (https://opencpn.org).
  2. Extract the GPX file.
  3. Compute distances, bearings, and durations to create a route.
"So?" you ask.

So. When I did this, I researched the math and got a grip on the haversine formula for doing the spherical geometry computation of distances between points on a sphere.

It's not too bad. The formula are big-ish. But manageable. See http://www.edwilliams.org/avform.htm#Dist for the great circle distance formula.


For airplanes and powered freighters crossing oceans, this is perfect.

For a small sailboat going from Annapolis, Maryland, to the Bahamas, this level of complexity is craziness. While accurate, it doesn't really solve the problem I have. 

I don't actually need that much accuracy. 

I need this much accuracy.


And no more. This is the essential hypotenuse distance using an R-factor to convert the difference between latitudes and the distance between longitudes into pretty-close distances. For nautical miles, R is 60×180÷π. 

This is simpler and it solves the problem I actually have. Up to about 232 miles, the answer is within 1 mile of correct. The error grows quickly. Double the distance and the error seems to jump to 8 miles. A 464 mile sailing journey (at 6 knots) takes 3 days. Wind, weather, tides and currents will introduce more error than the simplifying assumptions.

What's important is this can be put into a spreadsheet without pain. I don't need to write sophisticated Python apps to apply haversine to sequences of way-points. I can do a simpler hypotenuse computation on waypoints converted to radians.

Is there a lesson learned?

I think there is.

There's the haversine a super-general solution. It handles great-circle routes elegantly. 

But it doesn't solve my actual problem. And that makes it over-engineering.

My problem is what we call rhumb-line sailing. Over short-enough distances the world may as well be flat. Over slightly longer distances, errors in the ship's compass and speedometer make a hyper-accurate great circle route moot. 

(Even with several fancy GPS-based navigation computers, a prudent mariner has paper backups. The list of waypoints, estimated times and directions are essential when the boat's GPS reciever fails.)

I don't really need the sophistication (and the potential for bugs) with haversine. It doesn't solve a problem I actually have.

Tuesday, February 25, 2020

Stingray Reader Pervasively Bad Decision

I made some bad decisions when I wrote this a few years ago: https://github.com/slott56/Stingray-Reader. Really bad. And. Recently, I've burdened myself with conflicting goals. Ugh.

I need to upgrade to Python 3.8, and add type hints. This exposed somes badness.

See https://slott-softwarearchitect.blogspot.com/2020/01/stingray-reader-rewrite.html for some status.

The very first version(s) of this were expeditious solutions to some separate-but-related problems. Spreadsheet processing was an important thing for me f. Fixed-format file versions of spreadsheets showed up once in a while mixed with XLS and CSV files. Separately, COBOL code analysis was a thing I'd been involved in going back to the turn of the century.

The two overlap. A lot.

The first working versions of apps to process COBOL data in Python relied on a somewhat-stateful representation of the COBOL DDE (Data Definition Element.) The structure had to be visited more than once to figure out size, offset, and dimensionality. We'll talk about this some more.

A slightly more clever algorithm would leverage the essential parsing as a kind of tree walk, pushing details down into children and summarizing up into the parent when the level number changed. It didn't seem necessary at the time.

Today

I've been working for almost three weeks on trying to disentangle the original DDE's from the newer schema. I've been trying to invert the relationships so a DDE exists independently of a schema attribute. This means some copy-and-paste of data between the DDE source and the more desirable and general schema definition.

It turns out that some design decisions can be pervasively bad. Really bad-foundation-wrecks-the-whole-house kind of bad.

At this point, I think I've teased apart the root cause problem. (Of course, you never know until you have things fixed.)

For the most part, this is a hierarchical schema. It's modeled nicely by JSONSchema or XSD. However. There are two additional, huge problems to solve.

REDEFINES. The first huge problem is a COBOL definition can redefine another field. I'm not sure about the directionality of the reference. I know many languages require things be presented in dependency order: a base definition is provided  lexically first and all redefinitions are subsequent to it. Rather than depend on order of presentation, it seems a little easier to make a "reference resolution" pass. This plugs in useful references from items to the things they redefine, irrespective of any lexical ordering of the definitions.

This means we data can only be processed strictly lazily. A given block of bytes may have multiple, conflicting interpretations. It is, in a way, a free union of types. In some cases, it's a discriminated union, but the discriminating value is not a formal part of the specification. It's part of the legacy COBOL code.

OCCURS DEPENDING ON. The second huge problem is the number of elements in an array can depend on another field in the current record. In the common happy-path cases, occurrences are fixed. Having fixed occurrences means sizes and offsets can be computed as soon as the REDEFINES are sorted out.

Having occurrences depending on data means sizes and offsets cannot be computed until some data is present. The most general case, then, means settings sizes and offsets uniquely for each row of data.

Current Release

The current release (4.5) handles the ODO, size, and offset computation via a stateful DDE object.

Yes. You read that right. There are stateful values in the DDE. The values are adjusted on a row-by-row basis.

Tomorrow

There's got to be a better way.

Part of the problem has been conflicting goals.

  • Minimal tweaks required to introduce type hints.
  • Minimal tweaks to break the way a generic schema depended on the DDE implementation. This had to be inverted to make the DDE and generic schema independent.
The minimal tweaks idea is really bad. Really bad. 

The intent was to absolutely prevent breaking the demo programs. I may still be able to achieve this, but... There needs to be a clean line between the exposed work-book like functionality, and some behind the scenes COBOL DDE processing.

I now think it's essential to gut two things:
  1. Building a schema from the DDE. This is a (relatively) simple transformation from the COBOL-friendly source model to a generic, internal model that's compatible with JSONSchema or XSD. The simple attributes useful for workbooks require some additional details for dimensionality introduced by COBOL.
  2. Navigating to the input file bytes and creating Workbook Cell objects in a way that fits with the rest of the Workbook abstraction.
The happy path for Cell processing is more-or-less by attribute name: row.get('attribute').  This changes in the presence of COBOL OCCURS clause items. We have to add an index. row.get('ARRAY-ITEM', index=2) is the Python version of COBOL's ARRAY-ITEM(3).

The COBOL variable names *could* be mapped to Python names, and we *could* overload __getitem__() so that row.array_item[3] could be valid Python to fetch a value.

But nope. COBOL has 1-based indexing, and I'm not going to hide that. COBOL has a global current instance of the row, and I'm not going to work with globals. 

So. Where do I stand?

I'm about to start gutting. Some of the DDE size-and-offset (for a static occurrences)

Tuesday, January 14, 2020

The Wrong Abstraction Problem

For the last week I've been working with some legacy code that reveals a kind of problem I hadn't really seen before.

I'm calling it the Wrong Abstraction.

I want to contrast this with the Leaky Abstraction, where implementation details are revealed and raise havoc.

The Wrong Abstraction problem seems to arise when a specification is too technical. A detailed, code-like tangle of if-then-else becomes its own problem. I'm guessing someone worked to detail all the technical considerations. The chosen format as code-like text was not a great idea. The cyclomatic complexity of the specification is through the roof. And the code reflects this failure to actually capture anyone's underlying intent.

Cue the gif from the office. https://gph.is/1m89uqR Someone with "people skills" tried to recast the business intent into technical if-then-else.

Details

The context doesn't matter very much, but it can help people visualize the problem.

We're talking about validation rules. A document arrives, perhaps it's source code, or perhaps it's a shopping cart, or perhaps it's a schema definition. The document is validated according to some fairly sophisticated rules.
  • There's the obvious syntax check: is it valid JSON or Python or whatever the language is.
  • There are isolated validity checks. Individual elements (statements, items in the cart, subschemas) have to be valid.
  • There are aggregate validity checks. Groups of items -- the cart overall -- must satisfy some additional criteria. In our case, nine additional rules.
Some of the rules are complex. I think they original intent was drafted by a committee. It's visible, and involves large piles of money and potential lawsuits. Serious rules.

There are at least two separate implementations, mostly in JavaScript. (I'm not here to curse out JavaScript. The language has a lot of wat -- https://github.com/denysdovhan/wtfjs -- but that's not the point.)

So, you ask, where's the Wrongness?

It's a vast gap between intent and implementation.

Mind the Gap

The source documents decompose the validation into 9 steps. There's an explicit "all or nothing" disclaimer. That's nice.

The code looks more-or-less like this:

valid = True
for item in cart:
    for r in (Rule1, Rule2, Rule3, Rule4, ..., Rule9):
        if applies(r, item):
            valid = valid and r(item)

It turns out, though, we don't really apply all 9 rules like this. This is The Gap.

We actually have three types of items in the cart (or code or schema or whatever.) One type item has a default, a hidden feature of rule 1. It breaks down like this.
  • Rule 1 applies to an item of Type A. If the Type A item is omitted, the default value will pass the Rule 1 check. 
  • Rule 2 applies to all the items of Type B. Only.
  • Rules 3 to 8 apply to the items of Type C. Only. And they work in pairs, 3-4, 5-6, 7-8.
  • Rule 9 applies to a subset of items of Type C. The C9 subset.
Code with a nested "for all items" and "for all rules" is -- well -- wrong. It's flat-out lying about the validation rules and the objects (and collections) being validated. It's lying to a level that seems unconscionable to me. But. Maybe there's a reason.

The validation is really something more like this.

valid = Rule1(filter(lambda item: item.is_a, cart))
    and Rule2(filter(lambda item: item.is_b, cart))
    and all(
        r(x) 
        for r in (Rule3, Rule4, Rule5, ..., Rule8) 
        for x in filter(lambda item: item.is_c, cart)
    )
    and Rule9(filter(lambda item: item.is_c9, cart))

This reflects the actual structure of item types and rule types without wrapping them in a wrong abstraction.

(It's actually *more* complex than this, but, this is enough to expose the core issue.)

Why The Gap?

There are a number of causes. In part, the gap seems to reflect a disconnect between intention and implementation. Indeed, this seems to be an example of Conway's Law.
"Any organization that designs a system (defined broadly) will produce a design whose structure is a copy of the organization's communication structure."
I think the for item in cart: for rule in (Rule1, ..., Rule9):  structure reflects some intermediate design work between the original intent and the developer who implemented the code.

The extra layer of design work was a failed attempt to "simplify" things for the developer. I can imagine the conversation.

Designer: "It's simple. There are 12 rules. Each rule applies to each item."
Developer: "Rule one only seems to apply to Type A. So maybe it's not simple."
Designer: "It's simple. Don't make it complex. Write an 'applicability' test. Evaluate the rule if it applies to the item."
Developer: "So it's not trivially all rules against all items? Could we associate subsets of rules with the separate item types?"
Designer: "No. You're making it complex; It's simply evaluating all 12 rules against each item. If the rule applies to the item type. Other than that, it's simple."
Developer: "Instead of the 'applicability test,' could we group the rules?"
Designer: "No. You're making it complex."

I also think the gap also reflects an inability (or a lack of permission) to hack incrementally.

Incremental Development

One of Python's strong suits is the ability to run code at the >>> prompt. Confronted with a complex data structure and complex rules, some of us will try different designs on for size as quickly as we can. We hack out the essence of the code and see if it would make sense in a tutorial explanation.

I've darted down any number of dead-ends trying to get a sensible abstraction that I can understand and explain. The idea is to write a bit of code, mess around, and then decide to backtrack or push forward. (For a lot of people, rubber ducking or pair programming helps with this.)

When you're only a few lines of code into the problem, it's easy and fun to delete it all and start again. Or. It *should* be easy and fun. Some folks worry about deleting bad code and starting over.

I think the overall context didn't facilitate hacking around. The documentation talks about creating mock documents (or carts or collections) of items for testing purposes. I don't think anyone tried that. I'm not sure they knew the feature was available. I think they put the validation code into the framework, ran it in the development environment, looked at the debugging logs, changed the code, deployed, and ran things again until it worked. A long, painful slog, where backtracking would be considered a horrible set-back.

The complex "applies()" test has a surprising bunch of if statements that don't seem to reflect the actual properties of the three types of items. It seems to reflect an evolving series of guesses about attributes that were present or absent.

When I was younger, writing COBOL, PL/I, Fortran and the like, that's how we worked. Run it. Look at logs. Run it again later in the day. The long, slow development cycle meant that as soon as something looked like it was working, we called the project 90% complete.

This lead inexorably to the ninety-ninety rule.
"The first 90% of the code accounts for the first 90% of the development time. The remaining 10% of the code accounts for the other 90% of the development time.” 
Even if the abstraction is wrong. We've take 90% of the time to get something that works. There's no fixing it, now. We have to ship something, so we spend the next 90% of the time working around the wrongness and filling in gaps that shouldn't have existed.

A horrid development environment tends to prohibit refactoring. You can't simply run the test suite with refactored code because the test suite is neither fast nor fully automated. In this case, I don't think it runs in a handy form on the desktop, but requires a dedicated server. Without a Docker container for each developer, I think the project gets paralyzed and stuck with icky code and me doing a very expensive rewrite.

tl;dr

An utterly wrong abstraction seems have two root causes:

  • Too many designers
  • No ability to delete the garbage abstraction and start over with something better
  • No simple unit test environment to support refactoring

Tuesday, March 19, 2019

Don't Solve My Problem.

Two and a half examples of "Don't solve the problem I described. Provide the implementation I dream about."

Can't Use Enums for Constants

I was asked to see this because sometimes there's just too much abstraction https://stackoverflow.com/questions/2668355/how-much-abstraction-is-too-much

The accepted answer links to some useful design principles. Read the answer. It's useful.

The question objects to abstract superclasses without much (or any) actual implementation.  I've seen folks toy around with frameworks where there are classes that introduce a name, but little else. So I understand the complaint. I once tried to use Python classes as surrogates for Java interfaces. It was a bad idea. And irrelevant to solving the underlying problem.

The problem that lead to the "yet another abstraction" complaint, however, was not related to a design with empty layers of framework abstractions. It was not related to classes used to define an interface-like feature in Python. It wasn't related to *anything* in the Stack Overflow question or answer.

The "yet another abstraction" complaint was based on Python not having constants. Seriously. How did we get here? Right. They don't want a solution. They want to complain.

I lift this situation up to folks who are trapped in conversations where things devolve into bizarro-world like "Yet Another Abstraction is bad" when we're not talking about abstractions. The solution is simple, but, it's not what they wanted so, it's labeled as bad in some way.

The solution is bad because it's unexpected. Consequently peripheral, tangential, weird-ass nonsense will show up in trying to avoid an unexpected solution.

Can't Assign Numbers

There's an API to load some data.  They have 100's of clients happily loading data. In some cases, the clients must assign numbers in addition to names; it's a disambiguation thing. Most of the time, the name is good. In a few cases, (name, number) is a two-part key because they have multiple instances with the same name.

We're good here. The data structure's key can be (name, number) and the default number is zero. Works for almost everyone.

Almost everyone. Exception they have one client who cannot count or enumerate their data.

Really.

The client can't even pre-process the data to add numbers because reasons.

The stated reason is "the data originates off-line and the numbers might be inconsistent." The key needs a number. It doesn't need to consistent. The point is asking the client to own the identity -- a name and a number.

The solution seemed easy. Assign a number. If your data comes from a spread-sheet, use the row number. The =row() function works. Use that.  If your data doesn't come from a spread-sheet write a tiny utility to laminate a number into the data. This doesn't seem hard. And then the client owns the object identity.

Nope.

Can't do it. The web service will have to assign the number for them.

It's not a difficult feature to add. It's a complicated, stateful default value. This will turn into trouble tickets in the future when the numbers are unacceptable because they change with each load or something even more obscure than that.

Can't Fork a Repo

This isn't recent, and I may not have the details right. But.

The team had evolved an approach where they had several different pieces of software spread among multiple branches in a single Git repository.

This was weird. And they were -- of course -- about to start having CI/CD problems as they moved away from manual builds into a world of git commit hooks and relatively fixed CI/CD pipelines.

And they were really unhappy. They liked having multiple branches in a single repo. The idea of forking this into separate repos was unacceptable. Unworkable. Breaks everything. (Breaks everything they had. Everything they needed to replace. Or so they claimed.)

They had some vision of having the CI/CD jobs all reworked to move beyond the common dev/master world into their uniquely odd world of lots of parallel branches, each it's own private "master". But all in one repo.

They seemed to have locked into a strange world view, and weren't happy discarding it. The circular discussions of how multiple repos would break something something in their something was more examples of tangential, irrelevant discussion to cloak empty whining.

tl;dr

I think there are people who don't really want a "solution." They want something else.

There are people who have a vision: How Things Should Be (HTSB™,) They seem to be utterly unwilling to consider something that is not literally their (narrow) vision of HTSB.

It's very much as "Don't confuse me with facts, my mind is made up" situation. It's exasperating to me because of the irrelevant side-channel discussions they use to avoid confronting (or even stating) the actual problem.

Tuesday, February 12, 2019

On the uselessness of Enum -- wait, what?

Had a question about an enumerated set of constant values.

"Where do I put these constants?" they asked. It was clear what they wanted. This is another variation on their personal quest which can be called "I want Python to have CONST or Final." It's kind of tedious when a person asks -- repeatedly -- for a feature that's not present in the form they want it.

"Use Enum," I said.

"Nah," they replied. "It's Yet Another Abstraction."

Wait, what?

This is what I learned from rest of their nonsensical response: There's an absolute upper bound on abstractions, and Enum is one abstraction too many. Go ahead count them. This is too many.

Or.

They simply rejected the entire idea of learning something new. They wanted CONST or Final or some such. And until I provide it, Python is garbage because it doesn't have constants. (They're the kind of person that needs to see CONST minutes_per_hour = 60 in every program. When I ask why they don't also insist on seeing CONST one = 1 they seem shocked I would be so flippant.)

YAA. Seriously. Too many layers.

As if all of computing wasn't a stack of abstractions on top of stateful electronic circuits.

Tuesday, February 5, 2019

Python Enhancement Proposal -- Floating an Idea

Consider the following code

def max(m: int, n: int) -> int:
    if m >= n:
        return m
    elif n >= m:
        return n
    else:
        raise Exception(f"Design Error: {vars()}")

There's a question about else: clause and the exception raised there.
  • It's impossible. In this specific case, a little algebra can provide that it's impossible. In more complex cases, the algebra can be challenging. In some cases, external dependencies may make the algebra impossible.
  • It's needless in general. An else: would have been better than the elif n >= m:.  The problem with else: is that a poor design, or poor coordination with the external dependencies, can lead to undetectable errors.
Let's look at something a little more complex.

def ackermann(m: int, n: int) -> int:
    if m < 0 or n < 0:
        raise ValueError(f"{m} and {n} must be non-negative")
    if m == 0:
        return n + 1
    elif m > 0 and n == 0:
        return ackermann(m - 1, 1)
    elif m > 0 and n > 0:
        return ackermann(m - 1, ackermann(m, n - 1))
    else:
        raise Exception(f"Design Error: {vars()}")

It's somewhat less clear in this case that the else: is impossible. A little more algebra is required to create a necessary proof.

The core argument here is Edge Cases Are Inevitable. While we can try very assiduously to prevent them, they seem to be an emergent feature of complex software. There are two arguments that seem to indicate the inevitability of edge and corner cases:

  • Scale. For simple cases, with not too many branches and not too many variables, the algebra is manageable. As the branches and variables grow, the analysis becomes more difficult and more subject to error. 
  • Dependencies. For some cases, this kind of branching can be refactored into a polymorphic class hierarchy, and the decision-making superficially simplified. In other cases, there are multiple, disjoint states and multiple conditions related to those states, and the reasoning becomes more prone to errors.
The noble path is to use abstraction techniques to eliminate them. This is aspirational in some cases. While it's always the right thing to do, we need to check our work. And testing isn't always sufficient.

The noble path is subject to simple errors. While we can be very, very, very, very careful in our design, there will still be obscure cases which are very, very, very, very, very subtle. We can omit a condition from our analysis, and our unit tests, and all of our colleagues and everyone reviewing the pull request can be equally snowed by the complexity. 

We have two choices.
  1. Presume we are omniscient and act accordingly: use else: clauses as if we are incapable of error. Treat all complex if-elif chains as if they were trivial.
  2. Act more humbly and try to detect our failure to be omniscient.
If we acknowledge the possibility of a design error, what exception class should we use?
  • RuntimeError. In a sense, it's an error which didn't occur until we ran the application and some edge case cropped up. However. The error was *always* present. It was a design error, a failure to be truly omniscient and properly prove all of our if-elif branches were complete.
  • DesignError. We didn't think this would happen. But it did. And we need debugging information to see what exact confluence of variables caused the problem.
I submit that DesignError be added to the pantheon of Python exceptions. I'm wondering if I should make an attempt to write and submit a PEP on this. Thoughts?

Tuesday, January 16, 2018

I've decided on Windows -- Please help justify my choice

After many words, the email chain I received netted out to this:
  1. I can't teach myself data science on my crappy old Windows machine.
  2. I've decided to get a new Windows machine. Here are the specs.
My response was a mixture of incredulity and bafflement.

It appears that two things happened while I wasn't paying attention.
  1. Apple ceased to exist.
  2. The cloud ceased to exist.
I'm aware that many people think the Apple alternative is a non-starter. They are sure that after 40+ years selling computes, Apple is doomed, and we'll only have Windows on the desktop. Seriously.

Some people have farcical explanations for why Apple Cannot be Taken Seriously.

In this specific instance, there was a large investment in Python and Java that somehow couldn't be rebuild in Mac OS X. Details were explicitly not provided. Which is a way of saying there were no tangible "requirements" for this upgrade. Just specification numbers.

Import note. None of this involved "data" or "science." That was the baffling part. No objective measurement of anything. No list of software titles. No projects. No dataset sizes. Nothing.

The anti-cloud argument was even stranger than the anti-Mac argument.

Somehow, a super-large AWS server -- let's say it was a x1.16xlarge -- being used an hour a day (365 day*1 hr/day*$1.82/hr = $664) was deemed *more* expensive that a 64Gb 6-core home-based machine that would sit idle 23 hours each day.

The best part of $664/yr being *more* expensive?

Expert Judgement.

No "data". No "science". No measurement. No supporting details.

I wish I'd kept the email describing how someone who knew something said something about pricing.  It was marvelous Highest Paid Person's Opinion nonsense.

AFAIK, they were using 8,766 hours per year to compare AWS computing vs. at-home computing. This meant that an m5.4xlarge should be considered as costing $1,939 each year. Presumably because they'd never shut it off.

It included terms like "half-way decent performance."

There's a depth of wrongness to this that's hard to characterize beyond no "data" and no "science".

Tuesday, October 31, 2017

Some Reading

Higher-Order Functions. A really cool idea. Javascript isn't my favorite language.

https://medium.freecodecamp.org/higher-order-functions-in-javascript-d9101f9cf528

This, on the other hand, is huge: trunk-based development.

https://codeburst.io/trunk-based-development-vs-git-flow-a0212a6cae64

I'm really tired of having a dev branch with periodic commits to master so we can deploy from master. It's so much nicer to tag a release and deploy that.

Here's the top 10 Python list for September 2017.

https://medium.mybridge.co/python-top-10-articles-for-the-past-month-v-sep-2017-e42c26816ab9?source=email-f2cdc4351994-1507375544705-digest.reader------0-37&sectionName=top&gi=9a6dd40e3790

Learning Python: Zero to Hero: https://medium.freecodecamp.org/learning-python-from-zero-to-hero-120ea540b567

Why we switched from Python to Go: https://codeburst.io/why-we-switched-from-python-to-go-60c8fd2cb9a9. We distribute a CLI for our API in Go because it's slightly simpler to provide executables in Go. However, our user community has Python already... We need to provide similar functionality in Python.

Technical Debt: https://medium.freecodecamp.org/what-is-technical-debt-and-why-do-most-startups-have-it-9a54458daabf

Software Engineering v. Programming. https://medium.com/@samerbuna/software-engineering-is-different-from-programming-b108c135af26

Annotations in Java? Ugh. The level of complexity seems to have gotten out of control. https://blog.softwaremill.com/the-case-against-annotations-4b2fb170ed67

Programming vs. the text of the code itself. https://medium.com/@karolismasiulis/programming-is-not-about-text-c205ba6aa3ba I'm don't by the reductionist 1-dimensional view of text. Yes -- in a narrow, technical sense, it's one-dimensional. If you want to be really reductionist, it's a stream of bytes, which are really just a base-256 number. I don't think the reductionist argument is helpful. However, I am sure that the declarative/imperative distinction is worthy of a lot of thought, and this is a nice comparison. (In spite of the javascript.)

Tuesday, October 24, 2017

Programming by Search, Copy, and Paste Leads to Epic Fail

In a way, this is about an epic fail attempting copy-and-paste coding. But really, this is about thinking outside the box. The issue -- to me -- comes from failing to see the box. Here's the body of the email, edited slightly.
"...how determine when a file has completed downloading. It would be helpful if code snippets in a unix shell and Python. 
"I did Google but none seemed to address the fundamental race conditions. They all involve a variant of try, sleep and try again. This is problematic for my particular case because the file sizes very significantly."
I'll ignore the grammar problems and focus on the intent of the "I did Google..." part. Based on some personal knowledge, I doubt there was more than a single search string tried. And I doubt that more than a single page of the response was looked at. Those are not important concerns.

The important concern is the shocking vagueness of the problem statement. These words are almost entirely meaningless:
"a file has completed downloading"
Imagine the variety of possible file transfer protocols that could be involved, and how many of them can be properly scripted. Take all the time you want. It can help to make a list of all the protocols that make this is a non-problem.

No protocol was named. Therefore, a protocol was assumed. And the presence of this kind of tacit assumption forms an implicit box restricting what they're doing. The restriction is so unyielding to them than they don't even need to mention it. It's as essential to them as air. They need it, but cannot see it, and refused to acknowledge it.

At this point, all we can do is make random guesses.

("Why didn't you ask them for clarification?" you ask.  Good point. It's a personal failure in this case. The back-and-forth would take days. Eventually, they would send me useless explanations of deep ineptitude or a need to engage in corporate politics. Or both. I'll admit that I'm a jerk about requiring folks to take a first step and make a stab at code. Without code, I find it largely impossible to determine what they're really talking about. The above question is a prime example of a disconnection from reality that's too exasperating to deal with except superficially.)

Identifying the Box

Guess #1. This may be about FTP (or SFTP) file transfers. Further, it may involve FTP file uploads to a server, where the client doesn't disclose a size. Yes, the word "downloading" seems to preclude this guess, but almost all other choices aren't even possible.

If it really was a client side download, this is trivially automated using any of the available FTP client programs, include wget, curl, sftp, etc. The Python ftplib seems to be a fully automated client for FTP. The documentation is packed with examples. It seems unlikely that the question is actually client-side.

It's also possible that a single search failed to reveal all these automatable FTP clients.

Guess #2. "determine when"? Who actually cares when the upload finishes? An upload matters to the next client doing a download, or -- perhaps -- to a process that's supposed to consume the uploaded file. Is that what this is about?

Is the real question "how to trigger processing of an uploaded file when using FTP?"

In this case, we're left with stacks of follow-up questions. Primarily: "Why are you using FTP?"

If they replace their silly FTP (or SFTP) server with a RESTful API, they won't have these problems. It takes a few days to write a secure file-upload Flask container. With a swagger spec. And unit tests. And Gherkin feature definitions, and a behave test suite to be sure it *really* works.  It doesn't need very many routes. On completion of upload, it can fork off subprocesses to process the uploaded files. This is not hard. Really. Flask + Celery will do this.

Understanding the problem seems to require stepping outside of some box. It appears this is a struggle because of a poorly-defined box: a box assumed without being stated.

Working With the Box

At this point, we can only pretend the problem is about triggering processing after an upload. Let's further pretend the FTP is a legal requirement. Or we can pretend that SFTP is imposed by an inept IT department who also loves living inside some poorly-defined box. We're stuck with FTP for inexplicable reasons.

What can we do to game an FTP server to trigger processing of files of unknown sizes?

  • Write our own FTP server. This isn't very hard. It is, however, far simpler to write a RESTful Flask service that handles the file upload as a POST request via curl or wget. Writing an FTP server's a pain in the ass because the FTP protocol is surprisingly complex. Even writing an FTP subset that serves very specific client needs can be painful.
  • Poll the upload directory. This implies a race condition. Polling (and the race condition) have no practical consequences. If you want "real-time", write a RESTful API and don't use FTP. Since you're insisting on FTP, a delay is going to be part of the solution.
I'm more than a little shocked that search was considered as a viable design strategy to solving this problem. It doesn't seem like searching for solutions is required at all. I'm probably overstating this, but it seems sort of trivial and obvious that either a second file is required or a better file protocol is required. This seems to be simple "thinking" not "googling."

There are bunches of ways to approach this. Here are a few ways to use a second file and some kind of naming convention to show that two files are part of one transfer.
  • Send a file with the size of the target file *before* the target file. When the target file matches the stated size, initiate processing.
  • Send a file with the size and MD5 checksum of the target file. etc.
  • Send a file *after* the target file with the size and checksum. When this file shows up, simply confirm that the first file is all there.
Yes, polling is required. However, there's no race condition: there are two separate conditions which must both be met. The files are provided serially, the conditions are met serially.

Here are a two approaches that use a file format that properly handles completeness.
  • Gzip the file. The file receipt polling loop repeatedly tries to unzip it. If the unzip fails, the file is incomplete. 
    • Don't want to spend too much CPU time? Wait until the size has been stable for two polling intervals and then try to unzip then.
  • Tar the file. Yes. A tar archive of a single file can be checked for integrity. When the archive can be checked and shown to be valid, the target element can be extracted and processed.
    • Don't want to spend CPU time validating? Again. Wait for a stable size for a few polling intervals.
And, of course, it's possible to invent an entirely home-brewed file-wrapping protocol. Here's an approach.
  • Wrap the content in MIME-style headers. These can provide a size or a terminator string to help identify the end of the transfer.
The point here is that googling for code isn't part of solving this problem. Indeed, it can't solve this problem. Merely thinking about the nature of the problem ("triggering processing", "knowing the size") seemed necessary and sufficient to frame a solution.

What's Essential

Here's what didn't happen:
  • State the actual problem. 
  • Identify the boxes. Write them down. In words. There may be more than one.
  • Locate code to work with the boxes. Find the libraries or packages. Install them. Write a hello world. example to be sure that the code is understood.
Then -- and only then -- can we start to imagine solutions and ask questions about the boxes or the code that might manage the boxes.

It's impossible to state this strongly enough: We can't think outside the box if we refuse to acknowledge the box.

Tuesday, September 12, 2017

The No Code Approach to Software and Why It Might Be Bad

Start here: https://www.forbes.com/sites/jasonbloomberg/2017/07/20/the-low-codeno-code-movement-more-disruptive-than-you-realize/#98cfc4a722a3

I'm not impressed. I have been not impressed for 40 years and many previous incarnations of this idea of replacing code with UX.

Of course, I'm biased. I create code. Tools that remove the need to create code reflect a threat.

Not really, but my comments can be seen that way.

Here's why no code is bad.

Software Captures Knowledge

If we're going to represent knowledge in the form of software, then, we need to have some transparency so that we can see the entire stack of abstractions. Yes, it's turtles all the way down, but some of those abstractions are important, and other abstractions can be taken as "well known" and "details don't matter."

The C libraries that support the CPython implementation, for example, is where the turtles cease to matter (for many people.) Many of us have built a degree of trust and don't need to know how the libraries are implemented or how the hardware works, or what a transistor is, or what electricity is, or why electrons even have a mass or how mass is imparted by the Higgs boson.

A clever UI that removes (or reduces) code makes the abstractions opaque. We can't see past the UI. The software is no longer capturing useful knowledge. Instead, the software is some kind of interpreter, working on a data structure that represents the state of the UI buttons.

Instead of software describing the problem and the problem's state changes, the software is describing a user experience and those state changes.

I need the data structure, the current values as selected by the user, and the software to understand the captured knowledge. 

Perhaps the depiction of the UI will help. 

Perhaps it won't. 

In general, a picture of the UI is useless. It can't answer the question "Why click that?" We can't (and aren't expected) to provide essay answers on a UI. We're expected to click and move on.

If we are forced to provide a essay answers, then the UI could come closer to capturing knowledge. Imagine having a "Reason:" text box next to every clickable button.

We all know what the essay answers will look like. They'll look like bad comments in code. And bad commit comments in Git. And bad documentation.

Some Option: ☑️ Reason: Required
Other Option: ☐ Reason: Not sure if its needed

The problem with fancy UI's and low-code/no-code software is low-information/no-information software. Maintenance becomes difficult, perhaps impossible, because it's difficult understand what's going on.

Tuesday, July 25, 2017

The "My Code Is Precious To Me" Conundrum

I suspect some people sweat so hard over each line of code that it becomes precious. Valuable. An investment wrung from their very soul. Or something.

When they ask for comments, it becomes difficult.

The Pull Request context can be challenging. There the code is, beaten into submission after Herculean toils, and -- well -- it's not really very good. The review isn't a pleasant validation with some suggested rewrites of the docstrings to remove dangling participles (up with which I will not put.) Perhaps the code makes a fundamentally flawed assumption and proceeds from there to create larger and larger problems until it's really too awful to save.

How do you break the news?

I get non-PR requests for code reviews once in a while. The sincere effort at self-improvement is worthy of praise. It's outside any formal PR process; outside formal project efforts. It's good to ask for help like that.

The code, on the other hand, has to go.

I'm lucky that the people I work with daily can create -- and discard -- a half-dozen working examples in the space of an hour.

I'm unlucky that people who ask for code review advice can't even think rationally about starting again with different assumptions. They'd rather argue about their assumptions than simply create new code based on different (often fewer) assumptions.

I've seen some simple unit conversion problems turned into horrible messes. The first such terrifying thing was a data query filter based on year-month with a rolling 13-month window. Somehow, this turned into dozens and dozens of lines of ineffective code, filled with wrong edge cases.

Similar things happen with hour-minute windows. Lots of wrong code. Muddled confusion. Herculean efforts doing the wrong thing. Herculean.

Both year-month and hour-minute problems are units conversion. Year-month is months in base 12. Hour-minute is minutes in base 60. Technically, they're mixed bases, simple polynomials in two terms. It's a multiply and an add. 12y+m, where 0 ≤ m < 12. Maybe an extra subtract 1 is involved.

The entire algorithm is a multiply and an add. There shouldn't very many lines of code involved. In some cases, there's an additional conversion from integer minutes to float hours. Which is a multiply by a constant (1/720.) Or integer months to float years after an epochal year (another add with a negative number and multiply by 1/12.)

I think it's common that ineffective code need to be replaced. Maybe it's sad that it has to get replaced *after* being written? I don't think so. All code gets rewritten. Some just gets written sooner.

I think that some people may need some life-coaching as well as code reviews.

Perhaps they should be encouraged to participate in a design walk-through before sweating their precious life's blood into code that doesn't solve the problem at hand.

Tuesday, May 30, 2017

Ancient Software and A Small Value of "Works"

I'm not sold about this argument at all.

The "constant replacement" issue has two sides to it. If you follow the thread, there's a certain amount of (appropriate) bashing of the acquisitiveness that -- when exploited ruthlessly -- is a damning indictment of capitalism. There's a lot of value in recognizing the core capitalistic "buy more stuff" part of this.

But there's more.

One problem with this tweet is the threshold for "things that work."

Consumer software tends to be rather complex. It's often fat with features. If the feature you use aren't obviously broken, then you can say the software "works." But it's heavily qualified. Your interesting feature set may be rather small when compared to the whole.

Also, the technology stack tends to be quite tall. Your consumer software sits on top of a consumer OS and consumer-friendly libraries. All of which have to "work" to claim that your software "works."

As with the app, you're only using a subset of OS and runtime library features. This wraps the threshold for "works" in more and more layers of qualification. Smaller and smaller percentages of the code are involved in "works."

I'd suggest there's no other context where things are quite so complex and interdependent as software. The narrow feature set that appears to "work" may be adjacent to numerous security flaws and bugs and unintended consequences. The constant replacement may be necessary bug fixes.

There's more.

Part of the "constant replacement" situation stems from the cost and complexity of innovation. I think that some companies have a rentier mind-set. Once the software is written, they hope to derive ongoing revenue from the software. This doesn't happen because other companies innovate, the product becomes obsolete. So they scramble around trying to make money without doing too much real work.

There are three scenarios where ancient software gets replaced:
  • A new version include bug fixes. See above; the previous version didn't really "work" for large values of work. Blame for using ancient software is deserved. Keeping the old security flaws is not a virtue.
  • A new version is incremental feature creep. This is (potentially) rampant capitalism. Add a little something and sell the product as "new and improved." Keeping the old software because the new features aren't helpful makes sense.
  • Some businesses have a rentier mind-set. They want an ongoing revenue stream. There aren't any material improvements. Keep the old software. Make these people do real work.
Traditional manufacturing business models rely on things wearing out. In the world of atoms, things need to be replaced. A good product has a long future because of parts. And Service. Possibly even customization. I lived on a sailboat made in 1982. I've been carefully rebuilding and replacing pieces all over the boat.

A software "platform" (e.g. OS, database, etc.) can have good long-term value. A software product, however, lives in a hyper-competitive marketplace where improvements appear constantly. The lazy route of non-innovative upgrades is tempting.

I think that there is a place to blame people for having too low a threshold for "works."

Tuesday, April 4, 2017

Coding and "Inspiration"

Data Science Renee (@BecomingDataSci)
Thread. Coding is inherently frustrating. Expect that. But with puzzle-solving healthy attitude, keep going. Don't give up on yourself! twitter.com/IsabellaGhemen…

This thread includes some interesting topics. What hit me was the idea of "inspiration-driven coding."
"Do you ever get frustrated when coding? Or is it all inspirational?" 
"go into obsessive mode until I fix the problem"
This is fascinating. I've been coding for -- well -- a looooong time. I no longer recall a time when I struggled. These quotes provide some insight into the barrier that some people find between them and a finished project.

I think that "hard-part-do-later" is bad advice. I'm a big fan of tackling the hard part first.

I find that I have to do several things to get software to work. And I do these so often that I rarely think about doing them, so I might be misstating what I'm really doing. But I think this is right:

  • Understand the problem. It helps to understand the problem being solved. It's not essential to understand all of the problem. In a lot of cases, the problem is a larger-scale "business" issue which stems from a regulatory or competitive climate that has a very huge context including human aspirations and the very nature of what it means to be human. In these cases, narrowing the focus of the problem helps. Stating the problem clearly really helps. Clarifying the context can help; but it may involve erecting random-seeming boundaries to keep the problem from involving too many imponderables.
  • Understand the solution. This is easy to turn into glib useless advice. But I think that one thing that really helps is to really carefully detail what "success" means. For small things (like functions or classes) it should be a dry, formal assertion about the state of the variables. Without a mathematical formalism, it's easy to get confused and write a function that doesn't do the right thing. For larger-scale features, the solutions pieces need pretty complete, formal descriptions of how we know that they worked. File formats. Messages. Swagger specifications for an API. 
  • Understand the technology. This can be hard. For simple programming, the technology is the set of language constructs. For more sophisticated programming, the technologies are the libraries and packages available. When it comes to big data, these can be very large and complex packages (like pandas and numpy) with lots and lots of features. It's very easy to overlook features when searching through documentation. For integration of components, it's an understanding of what the various tools really do. (Example: I'm trying to get a grip on Docker, and there are a lot of commands that do a lot of things, and I have to be careful to understand the difference between "run" and "start".)
But how? How do we "understand" these things?

I'm a big fan of writing down everything. I really like the idea of "literate programming:" write down the problem. Write down the overview of the solution. Write down the technologies that will be used. Detail the coding assertions and outcomes. Detail the components being used. Write. Write. Write.

The first drafts will be all natural language. Summaries. Overviews. Hand-wringing over alternatives and tradeoffs and possibilities. That's okay. Writing helps. Write. Write. Write. 

Describe how simple it "should" be. Describe how the inputs get transmogrified to the outputs. Fantasize. 

Then elaborate on the details of "how" this will get done. Confirm the fantasy statements of how the various bits and pieces fit together. Revise. Revise. Revise.

At some point, parts will start to map to code in obvious ways. and there will be a break from natural language to more formal code. This may happen gradually. Or it may happen all at once.

One of the best pieces of coding advice was something I saw many years go.

"Write all the comments first." 

The example that followed showed a "wire frame" program that had some declarations, but was mostly blocks of comments describing -- in vague, general ways -- what would go here eventually. I like this approach because it allows space to think at a high level about how things fit together as well as space to think about details of how each individual little thing works.

There's a kind of progressive filling-in-the-blanks as code evolves into the frame.

Then A Miracle Occurs

Perhaps most important is this. Starting with wire-frame comments and natural language narratives can lead to identification of gaps in understanding the problem, the solution, or the technology. I think that these conceptual gaps are where the frustration grows.

This is why I think that the big problem is caused by "hard-part-do-later" thinking. It can turn out that the "hard part" required a miracle. 

There's a famous S. Harris cartoon (visit http://www.sciencecartoonsplus.com/pages/gallery.php) which has the "then a miracle occurs" step in the middle of a process. 

A wire frame for code is a low-cost, low-investment, low-emotional-content product. As code fills in, it may become clear that the wire frame wasn't right. It's easier to discard a hundred lines of comments once we realize that they're not quite right. There's less emotional investment. It's easy to throw it away and start again.

Indeed, we may have to go through a few wireframes to be really clear on where we think the miracle will occur. This gives us a chance to identify the hard part of the problem. 

Once we've got the hard part identified, we can tackle that. It may involve one of three kinds of deeper understanding:
  • Understanding the problem better,
  • Understanding the solution in more detail, or
  • Understanding the technology more completely.
Any combination of these may be the reason why some part is hard. We'll have to fix our understanding before we can finish. We may as well tackle it first, since we're going to have to do it anyway.

It's best to look for alternatives before we've written too much code. There's an emotional commitment to code, even if it doesn't work right. It's hard to throw code away. Therefore, stall as long as possible. Solve the hard parts. Commit to code last.  

Wednesday, November 16, 2016